| Date | Time | Student Responsibility |
|---|---|---|
| 2026-11-27 | 11:59pm ET | Mini-Project #03 Due |
| 2026-12-01 | 6:00pm ET | Final Project Presentation Slides Due |
| 2026-12-07 | 11:59pm ET | Mini-Project Peer Feedback #03 Due |
| 2026-12-08 | 6:00pm ET | Pre-Assignment #11 Due |
| 2026-12-11 | 11:59pm ET | Mini-Project #04 Due |
| 2026-12-17 | 11:59pm ET | Final Project Summary Report Due [Tentative] |
| 2026-12-17 | 11:59pm ET | Final Project Individual Report Due [Tentative] |
| 2026-12-17 | 11:59pm ET | Final Project Teammate Peer Evaluations Due [Tentative] |
| 2026-12-21 | 11:59pm ET | Mini-Project Peer Feedback #04 Due |
Software Tools for Data Analysis
STA 9750
Michael Weylandt
Week 12 – Tuesday 2026-11-24, Thursday 2026-11-19
Last Updated: 2026-11-18
STA 9750 Week 12
Today: Lecture #10: Strings, Regular Expressions, and Text Processing
These slides can be found online at:
In-class activities can be found at:
Upcoming TODO
Upcoming student responsibilities - Tuesday Section:
Upcoming TODO
Upcoming student responsibilities - Thursday Section:
| Date | Time | Student Responsibility |
|---|---|---|
| 2026-11-26 | Thanksgiving | |
| 2026-11-27 | 11:59pm ET | Mini-Project #03 Due |
| 2026-12-03 | 6:00pm ET | Final Project Presentation Slides Due |
| 2026-12-07 | 11:59pm ET | Mini-Project Peer Feedback #03 Due |
| 2026-12-10 | 6:00pm ET | Pre-Assignment #11 Due |
| 2026-12-11 | 11:59pm ET | Mini-Project #04 Due |
| 2026-12-17 | 11:59pm ET | Final Project Summary Report Due [Tentative] |
| 2026-12-17 | 11:59pm ET | Final Project Individual Report Due [Tentative] |
| 2026-12-17 | 11:59pm ET | Final Project Teammate Peer Evaluations Due [Tentative] |
Other Important Dates
Other Important Dates:
| Date | Instructor Action |
|---|---|
| 2026-11-19 | Mini-Project Released #04 |
| 2026-11-20 | Estimated Return of Peer Comments #02 |
| 2026-11-24 | Estimated Return of Meta-Review Comments #02 |
| 2026-11-26 | Thanksgiving #01 |
| 2026-11-30 | Mini-Project Peer Feedback Assigned #03 |
| 2026-12-11 | Estimated Return of Peer Comments #03 |
| 2026-12-14 | Mini-Project Peer Feedback Assigned #04 |
| 2026-12-15 | Estimated Return of Meta-Review Comments #03 |
STA 9750 Week 12
Today: Lecture #10: Strings, Regular Expressions, and Text Processing
- Communicating Results (
quarto) ✅ RBasics ✅- Data Manipulation in
R✅ - Data Visualization in
R✅ - Getting Data into
R⬅️- Files and APIs ✅
- Web Scraping ✅
- Cleaning and Processing Text ⬅️
- Statistical Modeling in
R
Today
Today
- Course Administration
- Warm-Up Exercise
- New Material
- Strings and Encodings
- Regular Expressions
- Text Manipulation
- Wrap-Up
Course Administration
Mini-Project #03
MP#03 - Where My People At?
Due 2026-11-27 at 11:59pm ET
Topics covered:
- Data Import
- Using the
tidycensusPackage - Static files
- API Usage
- Using the
- Data Maipulation and Visualization
- Slicing and Dicing with
dplyr - Spatial visualization
- Slicing and Dicing with
Mini-Project #04
MP#04 - Visualizing Recent Political Shifts
Due 2026-12-11 at 11:59pm ET
Topics covered:
- Data Import
- HTTP Request Construction (Last Week)
- HTML Scraping (Tabular) ⬅️ (Today)
- Text Parsing (Next Week)
- \(t\)-tests
- Putting Everything Together
Course Support
- Synchronous - MW Office Hours 2x / week:
- Tuesdays 5pm: Zoom
- Thursdays 5pm: Zoom
- Asynchronous: Teams
See Week 02 Slides for advice on asking good questions - Good questions get faster answers
Ask early for help with MPs - fixing problems is slow and iterative
Course Project
End of Semester Course Project:
- In-Class Final Presentations
- Next Class (After 🦃) (2026-12-01, 2026-12-03)
- Individual Report: 2026-12-17
- Group Report: 2026-12-17
- Peer Evaluations: 2026-12-17
See detailed instructions for rubrics, expectations, etc.
Review Exercise
Apple Rankings
We’re going to parse the page https://applerankings.com to find the best type of apples.
See this week’s lab for details.
Breakout Rooms
| Breakout Rooms | |
| Please join the Breakout Room for your Project Team | |
| Breakout #01: Crude Awakening (T) + Collide-o-Scope (R) | Breakout #02: Breathe Easy (T) + Zipliners (R) |
| Breakout #03: CUNY-naughts (T) + xG Analytics (R) | Breakout #04: Beyond the Scale (T) + Unemployment Hub (R) |
| Breakout #05: Beat The Odds (T) + King Philip (R) | Breakout #06: Team Rocket (T) + Emergency Care Bears (R) |
| Breakout #07: EconoMates (T) + Data Vinci (R) | Breakout #08: CitiThatNeverSleeps (T) + NYC Housing Pulse (R) |
| Breakout #09: Table for One (T) + Team Nexus (R) | Breakout #10: Degrees of Freedom (T) |
Go to your team’s breakout room. I will adjust / merge rooms based to ensure every room has enough people.
’em Apples
Working with Strings
Strings
In R, strings and characters are basically interchangeable
- Arbitrary “bits of text” that can be stored in a vector
- Don’t normally need to think about encoding
stringr provides basic tools for string manipulation (str_ functions)
stringi provides advanced functionality
String Handling
Easy to get 90% of the way correct - very hard to get 100% correct
Human language is messy - choices are culturally-specific
Unicode standard exists to make it easy (easier…) to do the right thing
Unicode
Unicode is an attempt to standardize all human written language:
- So hard!
- Moving target
- Don’t implement yourself - use libraries
Latest Unicode tables: unicodeplus.com/
Encodings connect Unicode IDs with actual bits on your computer: UTF-8 is mainly back-compatible and should be your default
Unicode Controversies
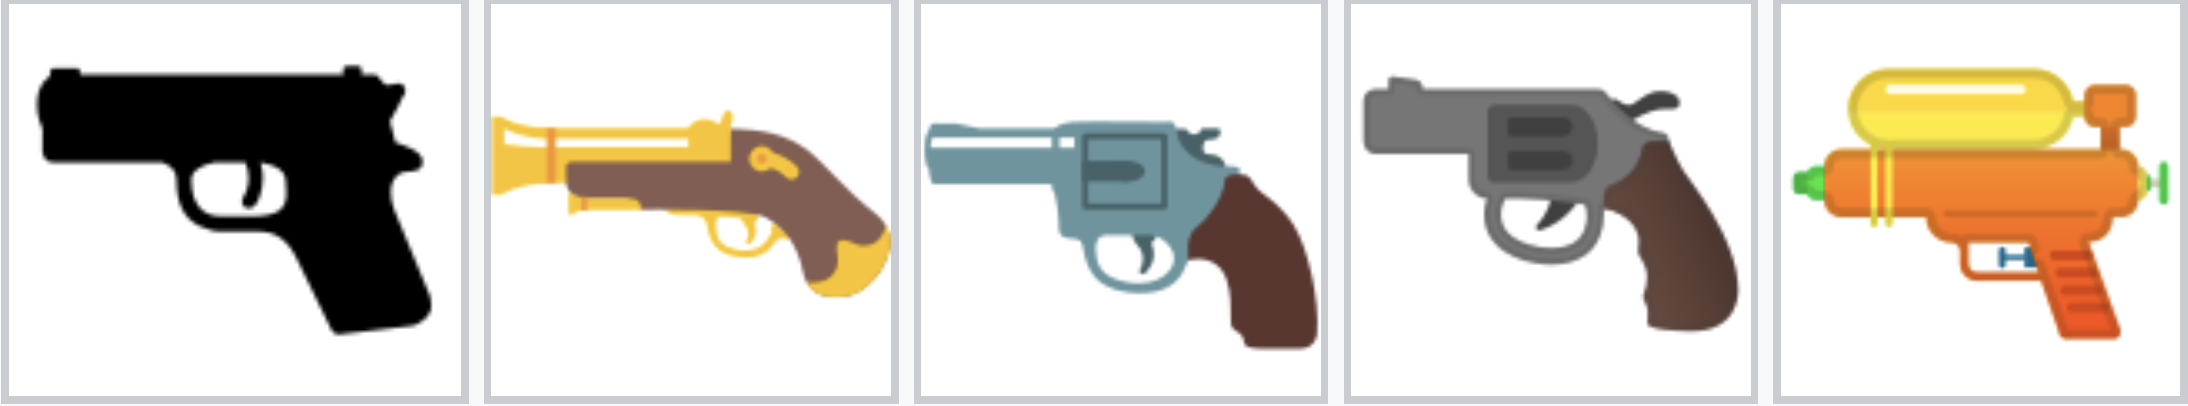
Pistol (U+1F52B) emoji:
- Originally a (regular) gun, Apple lead the charge to a water pistol, now standard
Unicode Controversies
Taco Controversy 🌮:
- Taco Emoji History
- Taco Emoji Controversy
Unicode Failures
Unicode+UTF-8 - Modern Standard
Best practices:
- Use updated Unicode compliant libraries like
stringr - Use UTF-8 strings
- If your data isn’t UTF-8, make it UTF-8 ASAP
stringr
The tidyverse package stringr provides a tools for string manipulation:
- All functions start with
str_ - “Input” string is always first argument
- Reasonably vectorized
stringr + dplyr
All stringr functions work well in dplyr pipelines (“vectorized”):
   lower_letters upper_letters
1              a             A
2              b             B
3              c             C
4              d             D
5              e             E
6              f             F
7              g             G
8              h             H
9              i             I
10             j             J
11             k             K
12             l             L
13             m             M
14             n             N
15             o             O
16             p             P
17             q             Q
18             r             R
19             s             S
20             t             T
21             u             U
22             v             V
23             w             W
24             x             X
25             y             Y
26             z             Z
String Splitting
str_split() to split at a pattern
[[1]]
[1] "apples"  "oranges" "pears"   "bananas"

[[2]]
[1] "pineapples" "mangos" "guavas" [,1] [,2]
[1,] "apples " " oranges and pears and bananas"
[2,] "pineapples " " mangos and guavas" See also str_split_i to get only one element of split
Trimming Strings
Common to have excess whitespace around results: str_trim
Sub-Strings
str_sub to get substrings:
Regular Expressions
Working directly with characters is painful and hard to do properly
Regular Expressions (regex) provide tools for specifying patterns in strings:
- Regular => following rules
Regex Tools
- Testing Regular Expressions Interactively: regex101.com/
- Alternative regexr.com/
- Automated Regular Expression Builder: regex-generator
- AI Regexp Builder: hregexgo.com/
LLMs are also very good at this if you can specify what you want properly.
Regex 101
A basic regex is just a pattern:
a: The regexawill match all strings with ana:
Replacement
str_replace will replace string with something else: - str_remove will replace with nothing - Does first match (cf str_{remove,replace}_all)
Wildcard
The . character is a ‘wildcard’ and matches anything:
(You might have seen a similar usage using formulas)
Alternatives
Alternatives can be expressed using a |:
Ranges
Sometimes we might want to match a wide range of characters; e.g. digits
Alternatives are painful: (0|1|2|3|4|5|6|7|8|9)
Ranges
Useful ranges:
[A-Z]: Uppercase letters[a-z]: Lowercase letters[0-9]: Digits
Can also ‘hard code’ a range by listing all elements:
[0123456789][aeiou]
Ranges
Some useful ranges are hard-coded:
[:alpha:][:lower:][:upper:][:digit:][:alnum:][:punct:][:space:]
I like these - quite clear:
Quantifiers
Quantifiers (multiple matches):
.{a, b}: anywhere fromatobcopies (inclusive).{, b}: no more thanbcopies.{a,}: at leastacopies.?: zero-or-one, same as.{0,1}.*: zero-or-more, same as.{0,}.+: one-or-more, same as{1,}
Quantifiers
Wildcard match optional:
Strings with numbers:
Regex Practice
With your breakout group, it’s time for some Regular Expression Practice
Breakout Rooms
| Breakout Rooms | |
| Please join the Breakout Room for your Project Team | |
| Breakout #01: Crude Awakening (T) + Collide-o-Scope (R) | Breakout #02: Breathe Easy (T) + Zipliners (R) |
| Breakout #03: CUNY-naughts (T) + xG Analytics (R) | Breakout #04: Beyond the Scale (T) + Unemployment Hub (R) |
| Breakout #05: Beat The Odds (T) + King Philip (R) | Breakout #06: Team Rocket (T) + Emergency Care Bears (R) |
| Breakout #07: EconoMates (T) + Data Vinci (R) | Breakout #08: CitiThatNeverSleeps (T) + NYC Housing Pulse (R) |
| Breakout #09: Table for One (T) + Team Nexus (R) | Breakout #10: Degrees of Freedom (T) |
Go to your team’s breakout room. I will adjust / merge rooms based to ensure every room has enough people.
Start and End Anchors
Anchors let us refer to the start and end of a string:
^: start$: end
Extracting Matches
Often, we use regex to pull our part of a string:
str_detectis there a ‘fit’?str_extractextract the whole ‘fit’str_extract(group=)andstr_matchextract specific groups
Extracting Matches
str_detect - is there a match?
[1] TRUEstr_extract - get the matched substring
Extracting Matches
Very useful for pulling numbers out of text:
Extracting Matches
str_match(group=) is useful for complex data extraction.
[1] "Michael Weylandt" "Kamiar Rad" [1] "STA9750" "STA9891"Also allows named groups - really helpful!
                                            V1       instructor  course
1 Michael Weylandt teaches STA9750 on Thursday Michael Weylandt STA9750
2      Kamiar Rad teaches STA9891 on Wednesday       Kamiar Rad STA9891
    weekday
1  Thursday
2 Wednesday
Exclusion
Not quite what we want
Homoglyphs
Why?
Homoglyphs
Particularly nasty with dashes - lean on [:punct:] where possible.
Why stringr?
Base R has its own set of regular expression functions (grep and friends)
stringr does the same thing, but with a more consistent interface.
Conversion table online
Regex in Scraping
Let’s practice using these functions in a web-scraping context.
Follow the lab to practice scraping https://quotes.toscrape.com with your breakout group
Items to practice:
- String detection (does this quote mention X)
- String manipulation (longest, shortest, etc.)
- Removing punctuation (
str_remove_all)
Breakout Rooms
| Breakout Rooms | |
| Please join the Breakout Room for your Project Team | |
| Breakout #01: Crude Awakening (T) + Collide-o-Scope (R) | Breakout #02: Breathe Easy (T) + Zipliners (R) |
| Breakout #03: CUNY-naughts (T) + xG Analytics (R) | Breakout #04: Beyond the Scale (T) + Unemployment Hub (R) |
| Breakout #05: Beat The Odds (T) + King Philip (R) | Breakout #06: Team Rocket (T) + Emergency Care Bears (R) |
| Breakout #07: EconoMates (T) + Data Vinci (R) | Breakout #08: CitiThatNeverSleeps (T) + NYC Housing Pulse (R) |
| Breakout #09: Table for One (T) + Team Nexus (R) | Breakout #10: Degrees of Freedom (T) |
Go to your team’s breakout room. I will adjust / merge rooms based to ensure every room has enough people.
Regex + Scraping
Regular expressions are incredibly useful when converting HTML text to workable data:
- Extract numbers
- Extract relevant parts of strings
Regex + Scraping
Common paradigm: html_text2() |> str_remove_all() |> as.numeric()
[1] 8.25 1000.00 500.00 12345.67Here, [^.[:digit:]-] means anything ([]) that is not (^) a period, a digit, or a -.
Regex + Scraping
Another common paradigm is to extract structured text into a data frame when html_table fails
    species    sex weight
1    Adelie female    200
2    Gentoo   male    500
3 Chinstrap female   1000
Regex + Scraping
Can also be used to manipulate strings within a data frame:
# A tibble: 2 × 4
  enrollment course   dept  numb
       <dbl> <chr>    <chr> <chr>
1         50 STA 9750 STA   9750
2         20 STA 9890 STA   9890
Cocktail Scraping
With your breakout group, it’s time to finish the cocktail scraping exercise🍸
Aim: Download all recipes from https://cocktails.hadley.nz/
Recall from Last Time:
- Make a mental map of site & Identify Selectors
- Develop a strategy to get all pages
- Function to pull out each recipe
- Function to parse earch recipe into a data frame
- Put it all together
Breakout Rooms
| Breakout Rooms | |
| Please join the Breakout Room for your Project Team | |
| Breakout #01: Crude Awakening (T) + Collide-o-Scope (R) | Breakout #02: Breathe Easy (T) + Zipliners (R) |
| Breakout #03: CUNY-naughts (T) + xG Analytics (R) | Breakout #04: Beyond the Scale (T) + Unemployment Hub (R) |
| Breakout #05: Beat The Odds (T) + King Philip (R) | Breakout #06: Team Rocket (T) + Emergency Care Bears (R) |
| Breakout #07: EconoMates (T) + Data Vinci (R) | Breakout #08: CitiThatNeverSleeps (T) + NYC Housing Pulse (R) |
| Breakout #09: Table for One (T) + Team Nexus (R) | Breakout #10: Degrees of Freedom (T) |
Go to your team’s breakout room. I will adjust / merge rooms based to ensure every room has enough people.
Wrap Up
Wrap Up
Processing Strings in R
- Encoding and Unicode
- Regular Expressions
- String Manipulations
- Capturing with Regex
Orientation
- Communicating Results (
quarto) ✅ RBasics ✅- Data Manipulation in
R✅ - Data Visualization in
R✅ - Getting Data into
R⬅️- Files and APIs ✅
- Web Scraping ✅
- Cleaning and Processing Text ⬅️
- Statistical Modeling in
R
Next Time
- Team Formation ✅
- Team Contracts ✅
- Proposal Presentations ✅
- Mid-Semester Check-Ins ✅
- Mid-Semester Peer Evaluations ✅
- Final Presentations ⬅️
- Final Reports
- Final Peer Evaluations
No Pre-Assignment
Life Tip of the Week
Tips for Technical Interviews
Some tips for technical interviews:
Communicate!
Test!
Anticipate the Danger Zone!
Communicate!
Talk / comment throughout a technical interview
- Live interview: vocalize thought process
- Async interview: comment all your choices
Advantages of Communication:
- Allow your interviewer to give “partial credit”
- Most questions aren’t fully-precise, seek clarification
- Share your thought process
Test!
Check your work as you go
- Mistakes that only appear ‘at scale’ are rare
- Test on small data, first terms of sequence, etc.
Easier to check simple output than code
Test!
Suppose you are asked to compute 100th number of a sequence
- Don’t code and submit
- Look at first 5 elements and check by hand
Suppose you are asked to analyze a data set
- Try your code on a small data set first
- Design your data to make correct answer evident
Danger Zone!
Know the ‘sharp edges’ of the tools you will be tested on:
NULLhandling inSQL- Missing values in
R - Groups of 0 or 1 observation
etc.
Technical Interviews
Your interviewer doesn’t ultimately care if you get the right answer on a puzzle
Do you have a process to get the right answer on a problem that matters?
- Do you handle edge cases?
- Do you resolve ambiguities in problem statement?
- Do you test well or just “code and pray”?